 CONTEXT MAPPER
Aggregate
The Aggregate pattern implementation from Sculptor has been adapted within CML to represent it with a separate grammar rule.
For a short introduction to the syntax of the other tactic DDD patterns, please have a look at Tactic DDD Syntax. For more details, we refer to the Sculptor project and its documentation.
Syntax
The aggregate supports the Responsibility Layers pattern and the Knowledge Level pattern. An aggregate can further contain Services, Resources, Consumers and SimpleDomainObjects (Entities, Value Objects, Domain Events, etc.) which are not further introduced here. The respective rules are defined by the Sculptor DSL, as already mentioned.
The following CML snippet illustrates an example of an aggregate to provide an impression how the rule can be used:
Aggregate Contract {
  responsibilities = "Contracts", "Policies"
  knowledgeLevel = CONCRETE

  Entity Contract {
    aggregateRoot

    - ContractId identifier
    - Customer client
    - List<Product> products
  }

  enum States {
    aggregateLifecycle
    CREATED, POLICE_CREATED, RECALLED
  }

  ValueObject ContractId {
    int contractId key
  }

  Entity Policy {
    int policyNr
    - Contract contract
    BigDecimal price
  }

  Service ContractService {
    @ContractId createContract(@Contract contrace) : write [ -> CREATED];
    @Contract getContract(@ContractId contractId) : read-only;
    boolean createPolicy(@ContractId contractId) : write [ CREATED -> POLICE_CREATED ];
    boolean recall(@ContractId contractId) : write [ CREATED, POLICE_CREATED -> RECALLED ];
  }
}
The equal sign (=) to assign an attribute value is always optional and therefore can be omitted.
Further examples can be found within our GitHub example repository context-mapper-examples.
Aggregate Lifecycle and State Transitions
As already illustrated in the example above, you can declare an Aggregate’s states with an enum. The aggregateLifecycle keyword marks the enum that defines the states:
enum States {
  aggregateLifecycle
  CREATED, POLICE_CREATED, RECALLED
}
In addition, every operation (no matter whether it is specified in a Service or an Entity) can declare whether it is a “read only” or “write” operation with the keywords read-only and write:
Service ContractService {
  @ContractId createContract(@Contract contrace) : write;
  @Contract getContract(@ContractId contractId) : read-only;
  boolean createPolicy(@ContractId contractId) : write;
  boolean recall(@ContractId contractId) : write;
}
A write operation may changes the state of the Aggregate. Such state transitions can be specified in square brackets:
Service ContractService {
  @ContractId createContract(@Contract contrace) : write [ -> CREATED];
  @Contract getContract(@ContractId contractId) : read-only;
  boolean createPolicy(@ContractId contractId) : write [ CREATED -> POLICE_CREATED ];
  boolean recall(@ContractId contractId) : write [ CREATED, POLICE_CREATED -> RECALLED ];
}
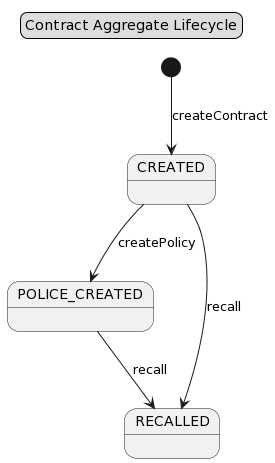
With our PlantUML generator you can visualize the lifecycle of your Aggregates with state diagrams. For example, the model at the top of this page generates the following state diagram:
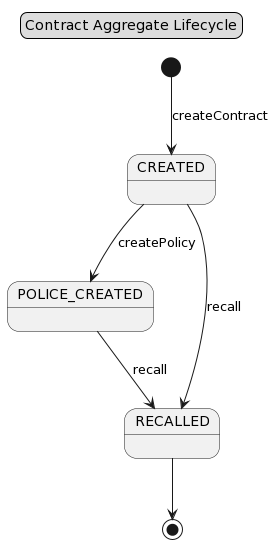
Note: If you use the target state markers (*) as documented above, we also use this information in our PlantUML Generator and generate the corresponding end states:
These language features allow you to define the lifecycle of an Aggregate. The following example show all possible variants of state transitions (note that the following example is not in line with the example above; it just shows all variants of possible state transitions):
// an initial state:
-> CREATED

// simple state transition from one state into the other
CREATED -> CHECK_REQUESTED

// the left side can contain multiple states:
// (this means that the state on the right can be reached by any of those on the left side)
CREATED, CHECK_REQUESTED -> CHECK_IN_PROGRESS

// multiple target states possible
// X stands for XOR and means one OR the other will be reached but not both at the same time (exclusive OR)
CHECK_IN_PROGRESS -> ACCEPTED X REJECTED

// target states can be marked as end states with a star:
CHECK_IN_PROGRESS -> ACCEPTED* X REJECTED*

// a combination of multiple on the left and multiple on the right
CREATED, CHECK_REQUESTED -> ACCEPTED X REJECTED
Hint: You can also model the state transition inside your event flows in the application layer.
Aggregate Owner
CML allows specifying an owner on the aggregate level. If aggregates are maintained by different teams, you can specify this as in the following example:
BoundedContext CustomerSelfServiceContext implements CustomerManagementDomain {
  type = APPLICATION
  domainVisionStatement = "This context represents a web application which allows the customer to login and change basic data records like the address."
  responsibilities = "AddressChange"
  implementationTechnology = "PHP Web Application"

  Aggregate CustomerFrontend {
    owner = CustomerFrontendTeam

    DomainEvent CustomerAddressChange {
      aggregateRoot

      - UserAccount issuer
      - Address changedAddress
    }
  }
  Aggregate Acounts {
    owner = CustomerBackendTeam

    Entity UserAccount {
      aggregateRoot

      String username
      - Customer accountCustomer
    }
  }
}
The owner attribute may be used for service decomposition by using the Split Bounded Context by Owners architectural refactoring.
Note that the owner attribute refers to a team, which must be a bounded context of the type TEAM: (see Bounded Context for more details):
/* Team Definitions */
BoundedContext CustomerBackendTeam {
  type = TEAM
}

BoundedContext CustomerFrontendTeam {
  type = TEAM
}
Aggregate Features
With CML you can further specify which features or user requirements (use cases and/or user stories) an Aggregate supports. This information may be used for service decomposition when applying the Split Bounded Context by Features architectural refactoring.
Use Cases can be assigned with the useCases keyword and User Stories with the userStories keyword. You can also use the features keyword and assign both, Use Cases and User Stories, at the same time:
BoundedContext PolicyManagementContext implements PolicyManagementDomain {
  Aggregate Offers {
    useCases = CreateOfferForCustomer

    Entity Offer {
      aggregateRoot

      int offerId
      - Customer client
      - List<Product> products
      BigDecimal price
    }
  }
  Aggregate Products {
    userStories = AddProductToOffer

    Entity Product {
      aggregateRoot

      - ProductId identifier
      String productName
    }
    ValueObject ProductId {
      int productId key
    }
  }
  Aggregate Contract {
    features = CreateOfferForCustomer, UpdateContract

    Entity Contract {
      aggregateRoot

      - ContractId identifier
      - Customer client
      - List<Product> products
    }
    ValueObject ContractId {
      int contractId key
    }

    Entity Policy {
      int policyNr
      - Contract contract
      BigDecimal price
    }
  }
}

UseCase CreateOfferForCustomer
UserStory UpdateContract
UserStory AddProductToOffer
Multiple User Stories and/or Use Cases can be assigned as a comma-separated list, as shown in the last Aggregate example above.
Use Case and User Story Declaration
The Use Cases and User Stories you refer to have to be declared on the root level of your CML file. Have a look at our user requirements page to see how you can declare and specify your cases and stories.
Security Zones
The attribute securityZone allows you to assign different Aggregates into different security zones. This language feature is primarily used to generate the user representations for Service Cutter, i.e. the separated security zones.
This can be very helpful to model security-related requirements which can later help in decomposing a Bounded Context.
A simple example:
BoundedContext MyMonolith {
  Aggregate CustomerManagement {
    securityZone "Internal"
    Entity Customer {
      String firstName
      String lastName
    }
    Entity Address {
      - Customer customer
      String street
      String city
    }
  }
  Aggregate CustomerFrontend {
    securityZone "Public"
    DomainEvent AddressChanged {
      - Address address
    }
  }
}
Security Access Groups
The attribute securityAccessGroup allows you to assign different Aggregates to different security access groups. This feature is primarily used to generate the user representations for Service Cutter, i.e. the security access groups.
This can be very helpful to declare that your Aggregates have different access requirements, which can later help when decomposing a Bounded Context.
An example:
BoundedContext MyMonolith {
  Aggregate CustomerManagement {
    securityAccessGroup "InsuranceEmployees"
    Entity Customer {
      String firstName
      String lastName
    }
    Entity Address {
      - Customer customer
      String street
      String city
    }
  }
  Aggregate CustomerFrontend {
    securityAccessGroup "Customers"
    DomainEvent AddressChanged {
      - Address address
    }
  }
}
Characteristics Classification
On the Aggregate level it is possible to classify parts of your domain model according to Service Cutter’s characteristics (compatibilities). This is primarily used to generate the user representations for Service Cutter, in case you generate service decomposition suggestions with Context Mapper.
For example: you can declare how often a certain Aggregate changes. Later, when you decompose your system, parts that change often should probably be separated from parts that basically never change. You find all the characteristics in the Service Cutter wiki.
In the following you find examples how you can classify Aggregates according to these criteria/characteristics in CML:
- Content Volatility
- Structural Volatility (a.k.a. Likelihood for Change)
- Availability Criticality
- Consistency Criticality
- Storage Similarity
- Security Criticality
Content Volatility
This characteristic corresponds to the Content Volatility criterion of Service Cutter.
The attribute contentVolatility takes the following values:
- RARELY
- NORMAL
- OFTEN
An example:
Aggregate AggregateDemo1 {
  contentVolatility = OFTEN // content changes more often in this Aggregate

  Entity DemoEntityOne
}

Aggregate AggregateDemo2 {
  contentVolatility = NORMAL

  Entity DemoEntityTwo
}
Likelihood for Change
With the attribute likelihoodForChange (or structuralVolatility) you can specify how volatile an Aggregate is (Structural Volatility). The attribute takes one of the following three values:
- RARELY
- NORMAL
- OFTEN
This attribute may be used for service decomposition, since parts which are likely to change should typically be isolated in separate components (see Parnas). Besides for proposing new service cuts, you can use this in CML by applying the Extract Aggregates by Volatility architectural refactoring.
The likelihood on an aggregate is declared as follows:
Aggregate CustomerFrontend {
  likelihoodForChange = OFTEN

  DomainEvent CustomerAddressChange {
    aggregateRoot

    - UserAccount issuer
    - Address changedAddress
  }
}
You can also use the structuralVolatility keyword:
Aggregate CustomerFrontend {
  structuralVolatility = OFTEN

  DomainEvent CustomerAddressChange {
    aggregateRoot

    - UserAccount issuer
    - Address changedAddress
  }
}
Availability Criticality
This characteristic corresponds to the Availability Criticality criterion of Service Cutter.
The attribute availabilityCriticality takes the following values:
- LOW
- NORMAL
- HIGH
An example:
Aggregate AggregateDemo1 {
  availabilityCriticality = HIGH // higher availability requirements then other aggregate

  Entity DemoEntityOne
}

Aggregate AggregateDemo2 {
  availabilityCriticality = NORMAL

  Entity DemoEntityTwo
}
Consistency Criticality
This characteristic corresponds to the Consistency Criticality criterion of Service Cutter.
The attribute consistencyCriticality takes the following values:
- LOW
- NORMAL
- HIGH
An example:
Aggregate AggregateDemo1 {
  consistencyCriticality = HIGH // higher consistency requirements then other aggregate

  Entity DemoEntityOne
}

Aggregate AggregateDemo2 {
  consistencyCriticality = NORMAL

  Entity DemoEntityTwo
}
Storage Similarity
This characteristic corresponds to the Storage Similarity criterion of Service Cutter.
The attribute storageSimilarity takes the following values:
- TINY
- NORMAL
- HUGE
An example:
Aggregate AggregateDemo1 {
  storageSimilarity = HUGE // similar storage requirements as AggregateDemo3

  Entity DemoEntityOne
}

Aggregate AggregateDemo2 {
  storageSimilarity = NORMAL

  Entity DemoEntityTwo
}

Aggregate AggregateDemo3 {
  storageSimilarity = HUGE // similar storage requirements as AggregateDemo1

  Entity DemoEntityThree
}
Security Criticality
This characteristic corresponds to the Security Criticality criterion of Service Cutter.
The attribute securityCriticality takes the following values:
- LOW
- NORMAL
- HIGH
An example:
Aggregate AggregateDemo1 {
  securityCriticality = HIGH // high security requirements

  Entity DemoEntityOne
}

Aggregate AggregateDemo2 {
  securityCriticality = NORMAL

  Entity DemoEntityTwo
}